Raw report: nmdc_community_metabolic_ecology Feeds into: callability-limited-comparative-inference, classifier-database-compatibility-in-taxonomic-quantification, community-metabolic-interdependence, computational-pathway-prediction-validation, condition-specific-fitness, cross-tenant-data-bridging, ecotype-environment-gene-content, environment-embedding-geography, habitat-structured-community-metabolic-potential, metabolic-model-gapfilling, multi-omics-integration, occurrence-versus-catabolic-activity, ontology-and-category-schema-sensitivity, study-batch-confounding-of-environmental-associations, taxonomic-nomenclature-reconciliation
Overview
This report integrates NMDC community taxonomic and metabolomics data with GTDB pangenome and GapMind pathway records to test community-scale Black Queen Hypothesis (BQH) dynamics and ecosystem differentiation. Under the BQH, costly functions are most likely to be lost when environmental supply is reliable. GapMind pathway completeness measures whether taxa possess all required steps for a pathway; the analysis used community-weighted completeness across 220 samples, 27,690 GTDB species, and 80 pathways. The integration included 305M GapMind pathway records and NMDC multi-omics data spanning soil and freshwater communities. The report describes this as, “to our knowledge,” the first application of GapMind community-weighted pathway completeness scores to predict environmental metabolomics across a large cross-habitat NMDC dataset. It presents the integration as a scalable approach for testing metabolic ecological hypotheses from public data lakehouses. 1
The community pathway matrix contained 220 samples and 80 pathways, comprising 18 amino-acid and 62 carbon-utilization pathways. The metabolomics overlap contained 175 samples, the H1 pathway–metabolomics matrix contained 131 samples, and the full analysis-ready merged matrix contained 174 samples. The full cohort included 126 Soil samples, 33 Freshwater samples, and 61 samples with unrecorded ecosystem type. All 33 Freshwater samples lacked paired metabolomics and were excluded from H1 but retained for H2. Mean taxonomy-bridge coverage was 94.6%; all 220 samples passed the 30% quality-control threshold, and 92% mapped at least 85% of community abundance to GTDB pangenome species. 1
The nmdc-arkin collection supplied data from four tables: centrifuge_gold gave community taxonomic profiles (species-level Centrifuge classifications), omics_files_table the sample-to-file bridge, study_table study metadata, and abiotic_features environmental measurements. Its metabolomics_gold table supplied per-sample LC-MS metabolomics (3.1M records across 48 studies). The KBase Data Lakehouse kbase-ke-pangenome collection supplied gapmind pathway completeness scores (305M rows) from gapmind_pathways, the GTDB taxonomy bridge from gtdb_species_clade, and per-species statistics from pangenome. 1
The report illustrates its results with these figures 1:
- a distribution of GTDB bridge coverage across 220 samples (
figures/bridge_quality_distribution.png) 1; - a heatmap of mean community pathway completeness by pathway × ecosystem type (
figures/pathway_completeness_heatmap.png) 1; - compound intensity distributions across samples (
figures/metabolomics_distribution.png) 1; - an H1 BQH correlation barplot of Spearman r per amino-acid pathway, with FDR-significant negative correlations (BQH support) in red (
figures/h1_bqh_barplot.png) 1; - scatterplots of the top (lowest-p) H1 pathways, namely the 4 pathways with the lowest p-values (
figures/h1_scatter_top.png) 1; - a principal-component analysis (PCA, which projects the samples onto the axes of greatest variance) plot by ecosystem type, a biplot of 220 samples × 80 pathways coloured by ecosystem type (
figures/h2_pca.png) 1; - a pathway-completeness boxplot of per-amino-acid-pathway completeness distributions by ecosystem type, with Kruskal-Wallis significance marked (
figures/pathway_completeness_boxplot.png) 1.
Methods and Data Products
The workflow ran as notebooks: 02_taxonomy_bridge.ipynb mapped NMDC Centrifuge taxa to GTDB pangenome species and computed per-sample bridge coverage; 03_pathway_completeness.ipynb extracted GapMind species-level pathway completeness and computed community-weighted scores for 220 samples × 80 pathways; and 05_statistical_analysis.ipynb ran the H1 Spearman correlation test with Benjamini-Hochberg false-discovery-rate (FDR, the expected share of false positives among significant calls) correction, the H2 PCA with Kruskal-Wallis (a rank-based test across groups) tests of ecosystem separation, and per-pathway boxplots. A classifier comparison table (data/nmdc_classifier_comparison.csv) summarised 3 NMDC taxonomy classifiers (kraken, centrifuge, and gottcha) by total rows, species-rank fraction, and file counts. 1
The project’s output tables include the following 1:
data/nmdc_sample_inventory.csv: ~220 NMDC samples with taxonomy and metabolomics coverage per study 1;data/bridge_quality.csv: per-sample GTDB species bridge coverage for 220 samples, all passing QC 1;data/species_pathway_completeness.csv: GapMind completeness per GTDB species per pathway, ~27,690 × 80 1;data/community_pathway_matrix.csv: community-weighted pathway completeness, 220 samples × 86 columns, with a long-format version (data/community_pathway_matrix_long.csv) of ~17,600 rows 1;data/metabolomics_matrix.csv: normalised metabolite intensities for 175 samples × 476 compounds 1;data/amino_acid_metabolites.csv: 737 sample × amino-acid-pathway log-intensity records for 15 matched amino-acid pathways 1;data/analysis_ready_matrix.csv: 174 rows merging pathway completeness, metabolomics, and abiotic features 1;data/h1_bqh_correlations.csv: Spearman r, p, and BH-FDR q for 15 amino-acid pathways, of which 13 were testable and 2 were skipped (glutamine n = 4, proline n = 9) 1;data/h2_pca_scores.csv: PC1–5 coordinates for 220 samples with ecosystem labels 1;data/h2_pca_loadings.csv: PC1 and PC2 loadings for all 80 pathways 1.
An early sample-overlap figure (figures/nmdc_sample_coverage_SUPERSEDED.png) was generated before the omics_files_table bridge was discovered in NB01 and shows 0 overlap; it was superseded by figures/bridge_quality_distribution.png from NB02, which reflects the correct 220-sample cohort, and renamed with a _SUPERSEDED suffix to signal its status. Likewise, data/nmdc_metabolomics_coverage.csv has 0 rows because it was saved before the omics_files_table bridge was found; it was superseded by data/analysis_ready_matrix.csv. 1
Key Findings
Community-scale Black Queen dynamics
Across 13 testable amino-acid biosynthesis pathways, 11 of 13 (85%) showed negative Spearman correlations between community pathway completeness and ambient amino-acid metabolite intensity, which is the direction the BQH predicts. A binomial sign test showed that this majority-negative direction was significantly non-random (p = 0.011), indicating a weak but consistent community-scale BQH signal. Leucine biosynthesis was negatively correlated with metabolite intensity (r = −0.390, q = 0.022, n = 62), and arginine biosynthesis was also negatively correlated (r = −0.297, q = 0.049, n = 80); these were the two pathways significant after Benjamini-Hochberg false-discovery-rate correction (q < 0.05). Methionine had the largest effect (r = −0.496, n = 18, q = 0.117) but was underpowered. Tyrosine was an outlier in the anti-BQH direction (r = +0.419, ns). That direction may reflect alternative tyrosine sources, such as phenylalanine hydroxylation, that complicate the biosynthesis-versus-availability relationship. Isoleucine became testable as the 13th pathway after the compound matching was corrected, but it showed no BQH signal at this sample size (r = −0.057, n = 18, q = 0.823). 1
| Pathway | n | Spearman r | p | BH q | FDR-significant 1 | |---|---|---|---|---|---| | met | 18 | −0.496 | 0.036 | 0.117 | — | | leu | 62 | −0.390 | 0.002 | 0.022 | Yes | | arg | 80 | −0.297 | 0.007 | 0.049 | Yes | | trp | 44 | −0.294 | 0.052 | 0.136 | — | | thr | 23 | −0.271 | 0.211 | 0.393 | — | | phe | 88 | −0.159 | 0.140 | 0.303 | — | | val | 54 | −0.151 | 0.275 | 0.446 | — | | ser | 59 | −0.061 | 0.645 | 0.762 | — | | asn | 73 | −0.061 | 0.610 | 0.762 | — | | ile | 18 | −0.057 | 0.823 | 0.823 | — | | chorismate | 65 | −0.038 | 0.765 | 0.823 | — | | gly | 114 | +0.081 | 0.389 | 0.562 | — | | tyr | 26 | +0.419 | 0.033 | 0.117 | — | | gln | 4 | — | — | — | skipped | | pro | 9 | — | — | — | skipped |
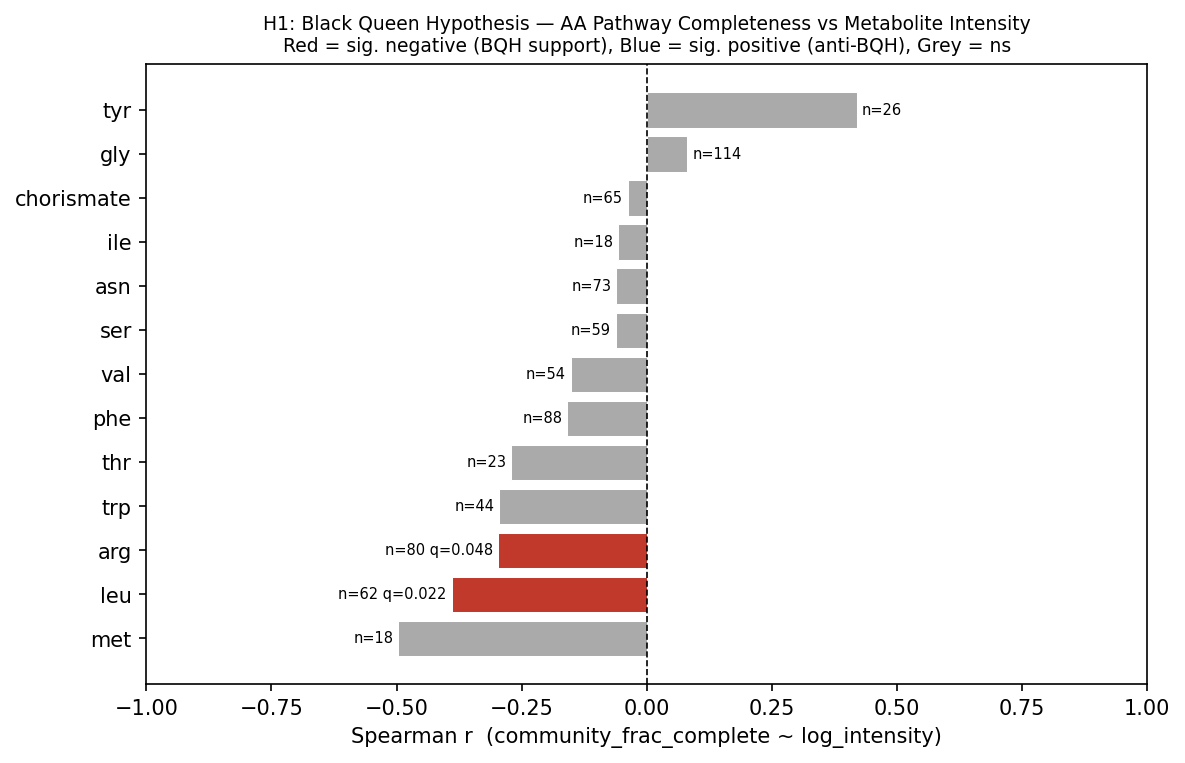 H1 BQH correlation barplot. From nmdc_community_metabolic_ecology.
The report urges caution about the tyrosine outlier (r = +0.42). Tyrosine can be produced from phenylalanine by non-biosynthetic hydroxylation. Communities with high phenylalanine-biosynthesis completeness, which the tyr completeness score does not capture, may therefore still supply tyrosine and decouple the biosynthesis-versus-pool relationship. This is a proposed explanation, not a tested result. 1
The H1 predictor was binary frac_complete, the fraction of community taxa with a GapMind score of 5, indicating a complete pathway with no missing steps. The alternative frac_likely_complete metric uses a score of at least 4 and was retained for sensitivity comparisons. Glutamine (n = 4) and proline (n = 9) were skipped because of insufficient metabolomics coverage. 1
Soil-only analysis used 125 Soil samples after excluding 6 Unknown-ecosystem samples. Leucine remained significant with r = −0.390, q = 0.022, n = 62; arginine remained directionally consistent but lost FDR significance (r = −0.264, q = 0.117, n = 78). The sign test remained 11/13 negative with p = 0.011. Excluding the 6-sample second study gave arginine r = −0.264, p = 0.019, n = 78. 1
The H1 dataset was dominated by one NMDC study: 125/131 samples (95%) came from nmdc:sty-11-r2h77870, while 6 came from nmdc:sty-11-547rwq94. All 62 leucine samples came from the first study, so cross-study LC-MS protocol heterogeneity was not a confounder for the leucine result; excluding the 6-sample second study gave arginine r = −0.264, p = 0.019, n = 78, so the arginine result was not driven by the minor study. 1
The report interprets the leucine and arginine results as weak but consistent support for community-scale BQH dynamics, with the energetic cost of synthesis offered as a mechanistic interpretation: leucine was reported as requiring 37 ATP equivalents and arginine 26 ATP equivalents. This is a mechanistic interpretation, not direct evidence of gene loss. The report also suggests that methionine, which has the largest effect (given as r = −0.50 in this passage; n = 18, q = 0.117), would likely reach significance with a larger metabolomics dataset; that prediction is untested. The leucine correlation strengthened from r = −0.326 to r = −0.390 and its q value from 0.045 to 0.022 after correcting an isoleucine/leucine compound-mapping collision. Three isoleucine compounds had been misassigned to leucine, and their near-zero completeness-versus-metabolite correlation had diluted the leucine signal. 1
The report calls its H1 results consistent with Mallick et al. (2019) and Noecker et al. (2016), both of which showed that community metabolomics is partially predictable from genomic or metagenomic functional profiles. It describes its GapMind pathway-completeness predictor as methodologically distinct from flux-based or PICRUSt-style models but arriving at comparable conclusions. 1
The report also compares its results with Gowda et al. (2022), which showed that metabolite dynamics in model communities are predictable from gene content. In that Literature Context passage it gives leucine r = −0.33 and arginine r = −0.30 and calls them weaker than, but directionally consistent with, the controlled-community finding. The leucine value there conflicts with the corrected leucine result reported elsewhere in the source (r = −0.390). The arginine value is likewise given as r = −0.30, whereas the H1 table gives r = −0.297. These values are recorded as the report states them and are not reconciled here. 1
Ecosystem differentiation of metabolic potential
PCA of the 220-sample × 80-pathway completeness matrix explained 49.4% of variance in PC1 and 16.6% in PC2, with PC1–5 explaining 83.0% in total. Kruskal-Wallis tests across three ecosystem types were significant for PC1 (H = 52.98, p < 0.0001) and PC2 (H = 123.74, p < 0.0001). Soil and Freshwater communities occupied nearly non-overlapping PCA regions; pairwise Soil versus Freshwater separation was Mann-Whitney U = 3,674, p < 0.0001, with median PC1 values of +3.86 for Soil and −6.28 for Freshwater. 1
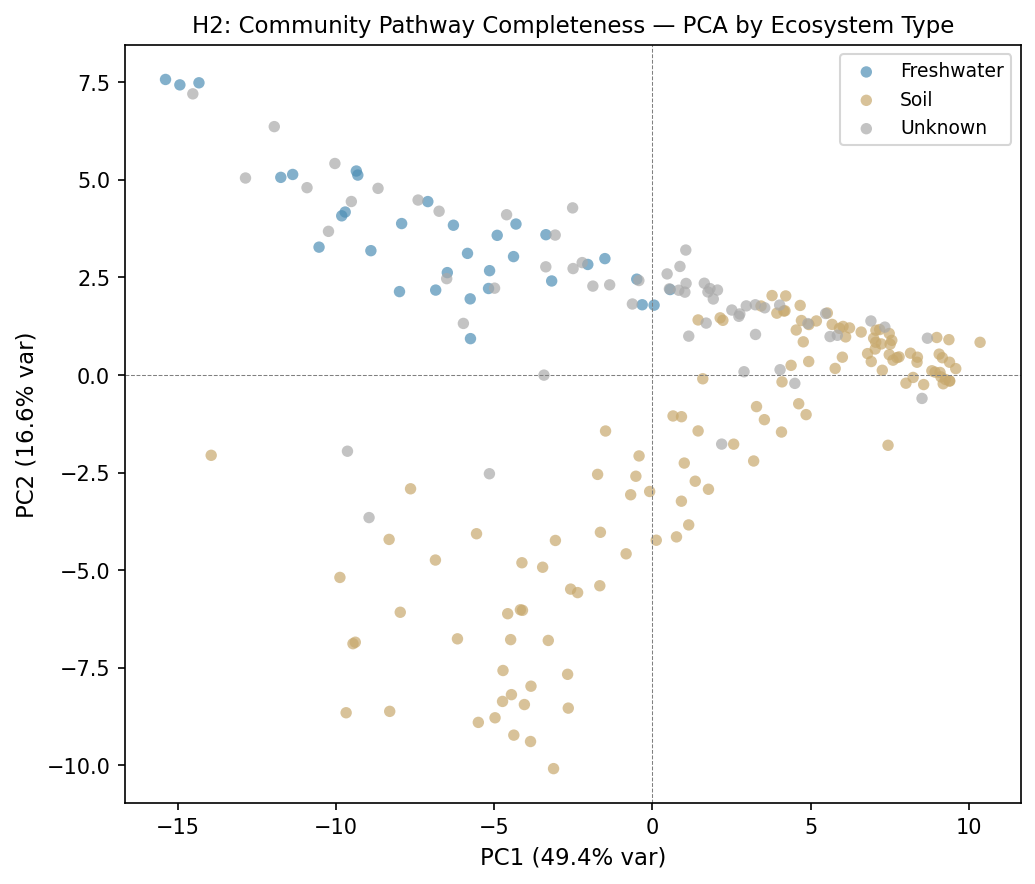 H2 PCA by ecosystem type. From nmdc_community_metabolic_ecology.
PC1 was dominated by carbon-utilization pathways, including glucuronate, fumarate, succinate, cellobiose, and galactose, with near-uniform positive loadings. The largest listed PC1 loadings were glucuronate (0.146), fumarate (0.144), succinate (0.143), lysine (0.140), and cellobiose (0.139). The report calls all five of these carbon-utilization pathways, although lysine is elsewhere counted among the amino-acid pathways and is among those left untestable in H1 for lack of compound detections. The report interprets this axis as indicating broadly higher carbon-substrate completeness in Soil communities, while amino-acid pathways contributed more strongly to PC2. 1
Per-pathway Kruskal-Wallis tests with Benjamini-Hochberg correction found significant ecosystem-type differences for 17 of 18 amino-acid pathways (q < 0.05). The strongest differences were glycine (H = 92.98, q = 1.2×10⁻¹⁹), asparagine (H = 66.19, q = 3.8×10⁻¹⁴), and cysteine (H = 62.66, q = 1.5×10⁻¹³) biosynthesis; tyrosine was the only pathway not significantly differentiated (q = 0.71). 1
The report interprets the strong PCA separation and 17/18 amino-acid pathway differences as evidence consistent with distinct metabolic configurations across aquatic and terrestrial habitats, while noting that the data do not establish whether the differences arise from habitat physicochemistry, taxonomic composition, or both. The report also proposes a hypothesis that the separation motivates but does not demonstrate. Under this metabolic niche hypothesis, habitat physicochemistry (aquatic vs. terrestrial) selects fundamentally different community metabolic configurations, not just different taxa. Carbon substrate availability would be the primary axis differentiating ecosystem metabolic type (PC1), with amino-acid biosynthesis playing a secondary, PC2-level role. 1
Caveats and Limitations
The 175 metabolomics samples derive from multiple NMDC studies, so metabolomics technical heterogeneity could affect broader multi-study analyses, although 95% of H1 samples (125/131) came from one NMDC study, and the second study contained only 6 samples. The report recommends study-level random-effects models when broader multi-study coverage becomes available. 1
All 33 Freshwater samples lacked paired metabolomics, so H1 was effectively a soil-only test. Whether BQH dynamics operate at the same scale in freshwater communities remains untested. 1
Abiotic features, including pH, temperature, and total organic carbon, were absent as usable measurements: all were NaN in the 174-sample analysis matrix. Consequently, partial correlations controlling for environmental gradients could not be performed, and abiotic variables may confound H1 and H2. 1
GapMind measures genomic potential rather than expression. The presence of pathway genes does not show that biosynthesis is active; metatranscriptomic data would be needed to test whether expressed pathway completeness correlates more strongly with metabolite pools. 1
Metabolite-to-pathway matching used string-based compound-name matching. An isoleucine substring collision with the leucine pattern was corrected in NB04 cell-14 using first-match-wins, and the reported results use the corrected run. After the fix, isoleucine was included as a 13th testable pathway (r = −0.057, ns). KEGG compound IDs had only a 2% annotation rate; cysteine, histidine, and lysine remained untestable because corresponding compounds were absent from detections. 1
Shikimic acid and 3-dehydroshikimic acid were used as metabolomics proxies for chorismate, but they are upstream intermediates rather than chorismate itself. Their concentrations therefore reflect precursor availability rather than the chorismate pool directly, making the chorismate correlation (r = −0.038) especially uncertain. 1
Approximately 1,352 Centrifuge taxa matched multiple GTDB clades within the same genus. One representative clade was selected by alphabetical tiebreaking on gtdb_species_clade_id; these genus-proxy-ambiguous taxa accounted for approximately 6.5% of mapped abundance. 1
Because of sample-size imbalance, glutamine (n = 4) and proline (n = 9) could not be tested: their metabolomics coverage was insufficient, even though they would be informative given their biological importance. Methionine also had limited power (n = 18, q = 0.117), and the report identifies larger metabolomics datasets as necessary to evaluate these pathways more reliably. 1
The habitat identity of the 61 Unknown-ecosystem samples is unresolved; the report proposes, but does not establish, that they likely represent a mix of soil subtypes or sediment environments. Resolving their habitat identity through NMDC ENVO annotations or study metadata could improve ecosystem comparisons and reveal finer-scale metabolic niche structure. 1
Future Directions
The report proposes several extensions. Because the current H1 dataset is effectively single-study, it proposes adding pH, temperature, and total organic carbon to partial-correlation or mixed-effects models once NMDC abiotic data are populated for the metabolomics-overlap samples, which could strengthen the H1 signal or identify confounders, and replicating H1 across additional NMDC studies with paired taxonomy and metabolomics to test whether the leucine and arginine signals generalise beyond the current cohort. Obtaining or generating metabolomics for the 33 Freshwater samples would allow a direct test of whether BQH dynamics differ between aquatic and terrestrial communities, which the report calls a key open question given their strikingly different pathway-completeness profiles. Pairing metatranscriptomics with metabolomics for a subset of samples would compare expressed pathway completeness, genomic potential, and metabolite abundance, directly testing whether expression rather than gene presence alone drives the BQH signal; this remains untested. Improving KEGG compound annotations in metabolomics_gold for the 3 currently missing amino-acid pathways (cysteine, histidine, and lysine) would expand the H1 test set from 13 to 16 testable pathways and improve statistical power. Resolving the habitat identities of the 61 Unknown samples via NMDC ENVO annotations or study-level metadata could improve H2 power and reveal finer-scale metabolic niche structure. 1
Slots Into
- multi-omics-integration — Supports integration of community taxonomy, pangenome pathway potential, and metabolomics by demonstrating a 220-sample NMDC workflow and testing pathway completeness against metabolite intensity. 1
- metabolic-model-gapfilling — Extends GapMind-based pathway completeness from species-level annotation to community-weighted metabolic potential and ecosystem-scale analysis. 1
- ecotype-environment-gene-content — Supports ecosystem-associated differentiation of community gene-content potential, including 17 of 18 amino-acid pathways and strong Soil–Freshwater PCA separation. 1
- condition-specific-fitness — Provides a related environmental-metabolism comparison in which pathway completeness and ambient metabolite availability are negatively associated for leucine and arginine, while identifying expression and abiotic controls as unresolved. 1
- community-metabolic-interdependence — 11 of 13 amino-acid pathways were negatively associated with ambient metabolite intensity (sign test p = 0.011), with leucine and arginine FDR-significant; tyrosine was an anti-BQH outlier and isoleucine a null. 1
- habitat-structured-community-metabolic-potential — Soil and Freshwater communities separated strongly on PC1 (49.4% of variance), and 17 of 18 amino-acid pathways differed by ecosystem type. 1
- study-batch-confounding-of-environmental-associations — 125/131 H1 samples came from one NMDC study, and the arginine signal persisted after excluding the minor study. 1
- biosynthetic-prototrophy-and-auxotrophy — Synthesis cost (37 and 26 ATP equivalents) is offered as a mechanistic interpretation of the leucine and arginine BQH signals, not as direct evidence of gene loss. 1
- cross-condition-metabolic-comparability — String-based compound matching produced an isoleucine/leucine collision, and KEGG compound IDs had only a 2% annotation rate. 1
- computational-pathway-prediction-validation — GapMind
frac_complete(score ≥ 5) was tested against metabolomics as a genomic-potential predictor distinct from flux-based models. 1 - classifier-database-compatibility-in-taxonomic-quantification — The Centrifuge-to-GTDB bridge reached 94.6% mean coverage, with ~1,352 genus-proxy-ambiguous taxa (~6.5% of mapped abundance). 1
- taxonomic-nomenclature-reconciliation — Ambiguous Centrifuge taxa were resolved to GTDB clades by alphabetical tiebreaking on
gtdb_species_clade_id. 1 - ontology-and-category-schema-sensitivity — Lysine is called a carbon-utilization pathway among the PC1 loadings but counted as an amino-acid pathway elsewhere in the report. 1
- callability-limited-comparative-inference — Freshwater lacked metabolomics, abiotic covariates were all NaN, and glutamine (n = 4) and proline (n = 9) were untestable. 1
- occurrence-versus-catabolic-activity — GapMind completeness reflects gene presence, not expressed biosynthesis. 1
- cross-tenant-data-bridging — Centrifuge taxa were bridged to GTDB pangenome species, and early outputs showed 0 overlap until the
omics_files_tablebridge was discovered. 1 - environment-embedding-geography — Habitat identity of 61 Unknown-ecosystem samples is unresolved; NMDC ENVO annotations are proposed to resolve it. 1